Calculus I · Maxima, Minima, and the Shape of a Function
Convex functions: one bowl, four faces
Now the centerpiece. A function is convex on an interval if it is shaped like a single upward bowl — and that shape can be described four different ways, all secretly the same. (A function is concave if is convex — a single downward dome; everything below flips.)
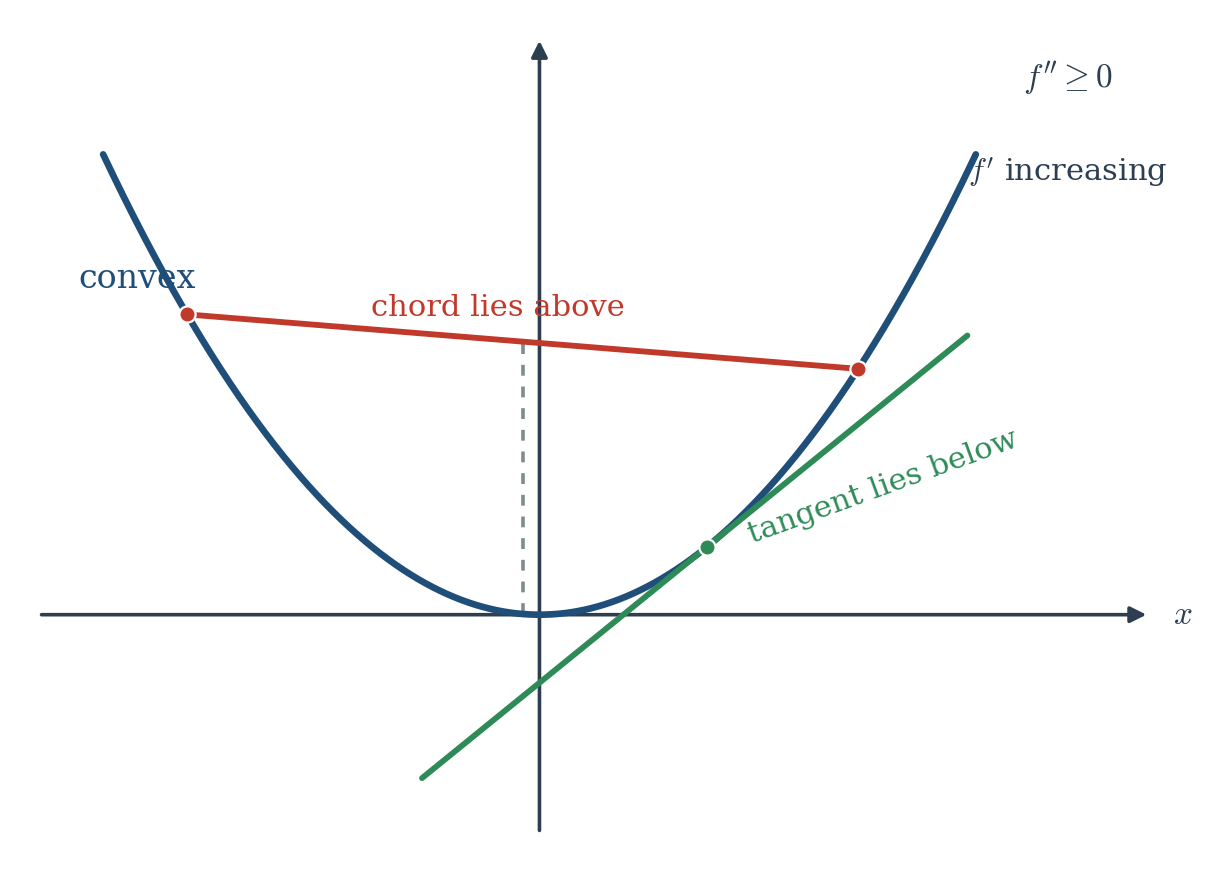
Four faces of convexity. For a (twice-differentiable) function , these are equivalent: 1. Chord above graph — the straight line between any two points on the graph lies on or above the graph. (This is the geometric definition.) 2. Tangent below graph — the graph lies on or above every one of its tangent lines. 3. Slopes increasing — is an increasing function (the curve only ever steepens left to right). 4. Nonnegative curvature — everywhere.
These look like four separate ideas and are one idea wearing four coats. The links are exactly the theorems of the last two chapters:
◆ Layer 2 — Why the four faces agree
Face 4 Face 3. “” says the derivative of is nonnegative, which by Chapter 6’s Consequence 2 (applied to ) says is increasing. Same statement. Face 4 Face 2. By Taylor (Chapter 7), the gap between and its tangent line at is the remainder for some . If , this gap is — the graph never dips below its tangent. (This is the inequality from Chapter 6, now understood as “ is convex.”) Face 2 Face 1 (chord above) is the geometric finish, and is left as a Diamond problem. The point: convexity isn’t a new mystery. It’s , dressed in geometry.
The theorem that matters: a convex bowl has no false floors
Here is why anyone cares. In a general function, the first-derivative test finds local minima — valley floors that might be nowhere near the lowest point overall. You could solve , find a dip, and be badly wrong about the true minimum. Convexity destroys that danger completely.
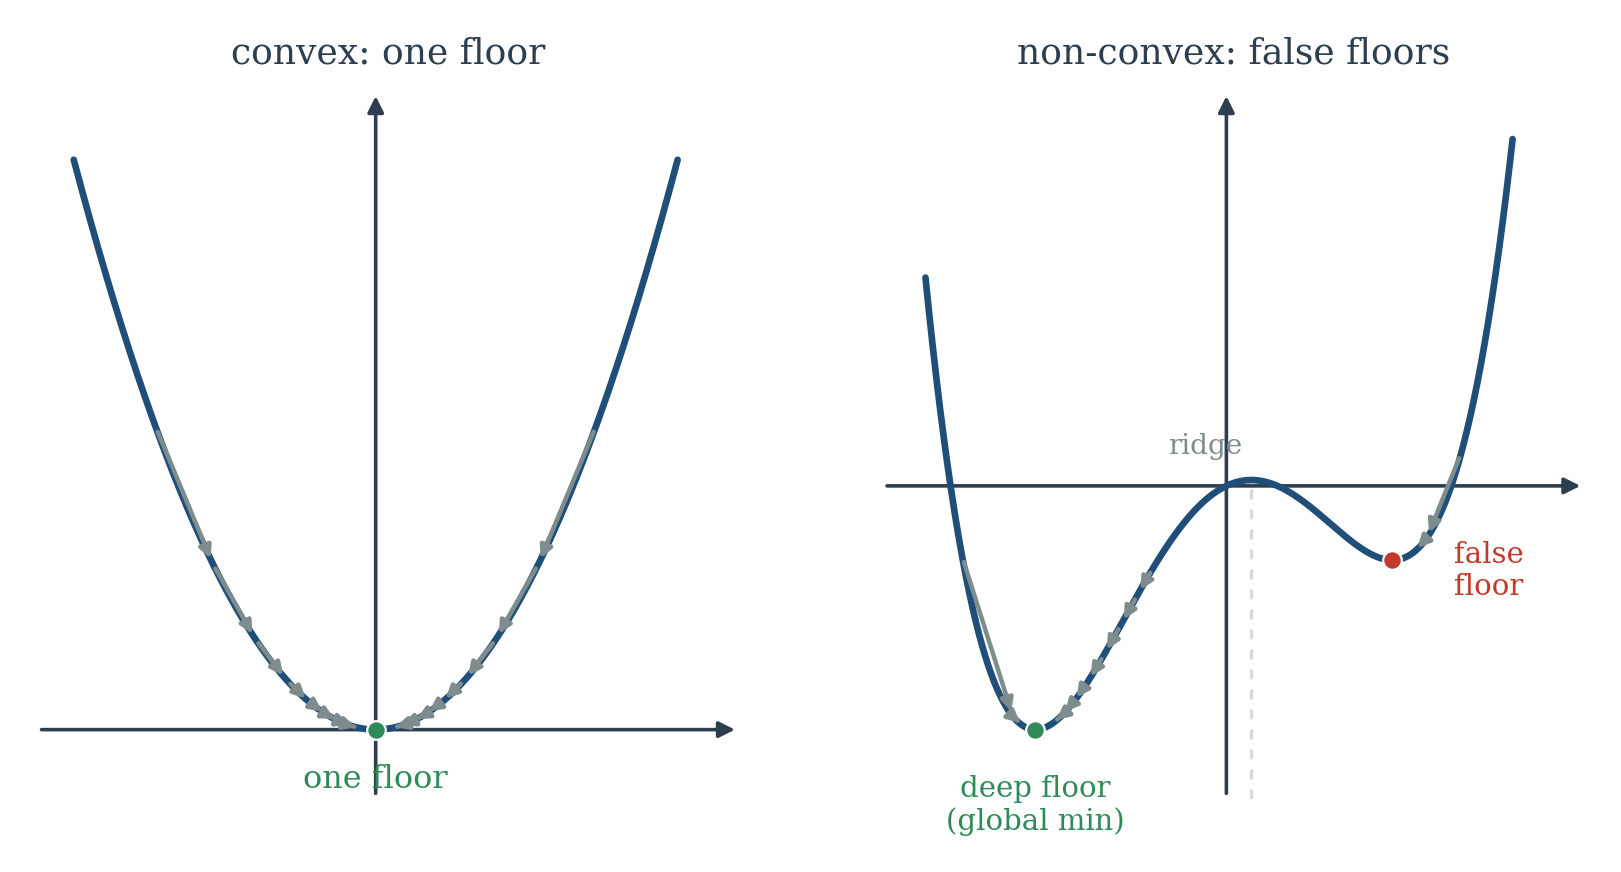
Theorem. If is convex and , then is the global minimum.
Proof. Since , the tangent line at is horizontal: it is the flat line . By Face 2 of convexity, the graph lies on or above every tangent line — in particular, above this one. So for every . That is exactly what it means for to be the global minimum.
Read what just happened. For a convex function, you don’t have to hunt for the best among many local minima, or worry that a better one lurks elsewhere. There are no others. Find one point where the slope is zero, and you have found the bottom of the world. A convex bowl has a single floor and no false ones.
Why this is the deepest idea in machine learning optimization
Recall the gradient-descent lab from Chapter 9 — the one where you ran the ball downhill on and watched it settle into different valleys depending on where it started. That function is non-convex: it has two separate dips, and gradient descent, which only ever steps downhill, falls into whichever one is nearest and stops, with no way to know a deeper valley exists across the ridge. That is the entire reason the starting point mattered.
Now contrast a convex loss. By the theorem above, it has exactly one minimum, and it is global. Gradient descent cannot get stuck, because there is nothing to get stuck in — every downhill path leads to the same single bottom. Convex problems are the ones where gradient descent is guaranteed to find the best answer. This is why, for decades, “is your problem convex?” was the first question in optimization.
And the punchline of modern AI is that neural networks are wildly non-convex — their loss landscapes have astronomically many local minima — and we train them with gradient descent anyway. There is no guarantee it finds the global best. The astonishing empirical fact, still not fully understood, is that the local minima it does find are usually good enough. Every time you hear that training a model is part science and part art, this is what’s meant: we left the safe, convex world on purpose, because the non-convex models are the ones powerful enough to matter. You now know exactly what was traded away, and why.